High-Quality AI Training Data Services - Collected, Labelled & Evaluated for Models That Perform
Talk to us10B+ Data Points Delivered for AI Training
Powering AI Innovation Across Every Domain & Modality.
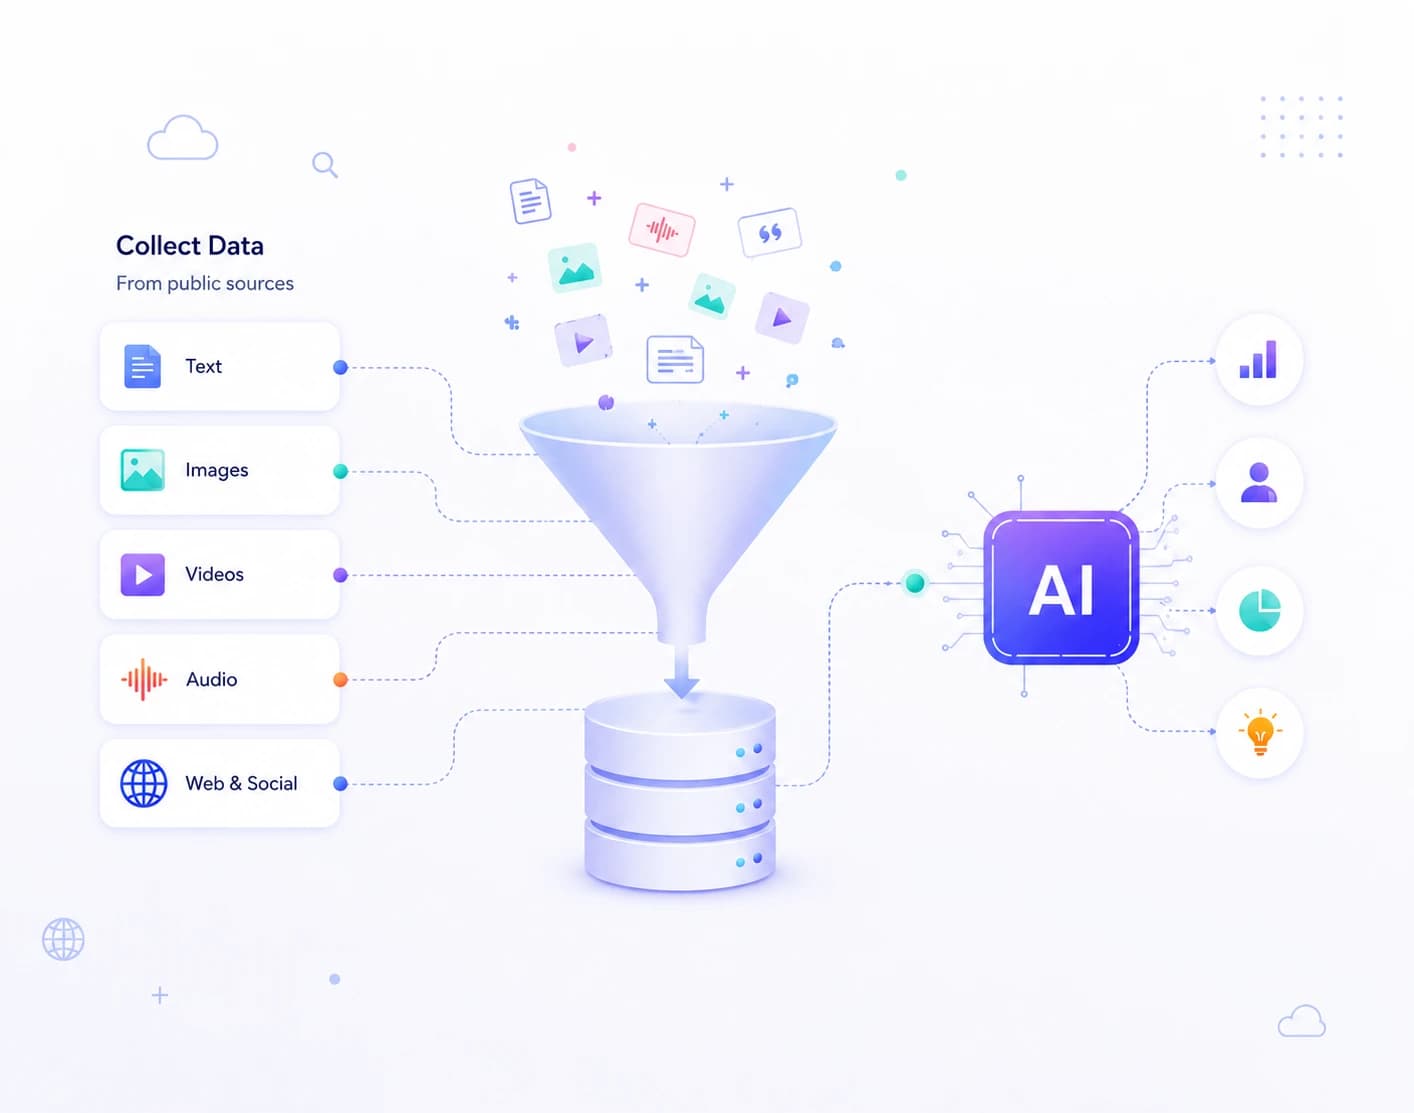
Great AI isn't built on algorithms. It's built on the data they learn from.
Up to 80% of AI development time is spent on data preparation - not model building. That's not a bottleneck. That's where the real work happens. The quality of your training data determines whether your model generalises or guesses, whether it responds accurately or hallucinates, whether it passes evaluation or fails in production.
TagX operates across the full AI data lifecycle - collection, curation, annotation, human feedback, and model evaluation. We don't just source datasets and deliver files. We build the ground truth data infrastructure your model depends on - with human-in-the-loop quality controls, domain-specific expertise, and the operational scale to keep pace with your training cycles.
Contact usThe full-cycle AI data capabilities that makes TagX different.

Human-in-the-Loop Data Annotation
Automated labeling gets you volume; human-in-the-loop gets you accuracy. TagX combines both, using expert human reviewers to validate, correct, and quality-check every label before it enters your training pipeline.

RLHF & Human Feedback Pipelines
Reinforcement Learning from Human Feedback aligns models with real-world expectations. TagX builds structured RLHF pipelines to collect, rank, and deliver high-quality human preference data.

Model Evaluation & Benchmarking
Uncover real model weaknesses before deployment. TagX creates task-specific evaluation datasets and adversarial test sets that challenge your models, so you know exactly what needs improvement.

Multi-Modal & Domain-Specific Datasets
From text and video to specialized healthcare or legal data, TagX builds custom datasets reflecting your exact operational context—never generic web scrapes repackaged as training data.
Your Data Pipeline for Reliable Web Intelligence
Schedule a callBetter data inputs. Superior AI performance.
Every AI model has a specific data requirement behind it, and the gap between a model that works in testing and one that performs in production is almost entirely determined by the quality of those inputs.
These are the six data services TagX delivers across the full AI training lifecycle.
From Requirement to Delivery, Four Steps. Zero Complexity
Scope Your Custom Data Blueprint
Tell us your target data sources, required attributes, volume, and frequency. Whether you need a massive one-off scrape or live streams, we help refine your requirements into a bulletproof data brief tailored to your exact business logic.
Validate with Live Sample Data & Custom APIs
We don't expect you to buy blind. We deliver a high-fidelity sample dataset in your preferred format (CSV, JSON) or set up a test API endpoint so your engineering team can instantly validate data quality, structure, and coverage.
Seamless Integration & Setup
Once you approve the sample, we finalize the scope, timelines, and SLAs. We map out the data delivery pipelines or configure your customized API access, making sure everything aligns perfectly with your technical infrastructure.
Production & On-Demand Data Delivery
Our team handles the heavy lifting—managing proxies, bypassing anti-bots, and maintaining the infrastructure. We deliver clean, structured data directly to your cloud storage (S3, GCS) or serve it dynamically via production-ready APIs on your precise schedule.
Every Industry Has Unique Data Needs. TagX Meets All of Them.
Trusted by AI teams
“We train models on a lot of web-sourced text and TagXData is basically our data feed now. We pick the sources, they push structured data to our S3 bucket, we don't think about it. My engineers actually build models again instead of patching Playwright scripts at midnight. Can't overstate how much that's changed the week.”
AI and cloud technology group
Frequently asked questions
What Makes TagX the Right Data Partner for You
From the first consultation to ongoing delivery, everything is completely managed by our engineering team.

100M+ Websites & Global Reach
Extract data at scale from websites across the globe. We bypass regional restrictions to deliver localised, market-relevant intelligence wherever your business operates.

Reliable Quality & Seamless Integration
Receive validated, structured data ready to plug directly into your systems or APIs — no manual cleaning, no reformatting, no friction.

24/7 Continuous Streams & Expert Support
Our pipelines run around the clock with proactive monitoring and dedicated support, so your data streams stay live, accurate, and uninterrupted.